Blog, Pitang.
Pitang Agile It
Challenges of using Optical Character Recognition (OCR)
OCR

Optical Character Recognition (OCR) is a technological marvel that has been revolutionizing the way we interact with physical documents and scanned images. However, behind this super functionality, there are complex challenges that engineers and developers have been facing. These complexities go beyond the printed words.
4 challenges of OCR
1. Image Quality and Text Legibility
One of the first challenges that OCR faces is directly linked to image quality. Often, the documents that need to be digitized are in degraded conditions due to time, moisture, or physical wear and tear.
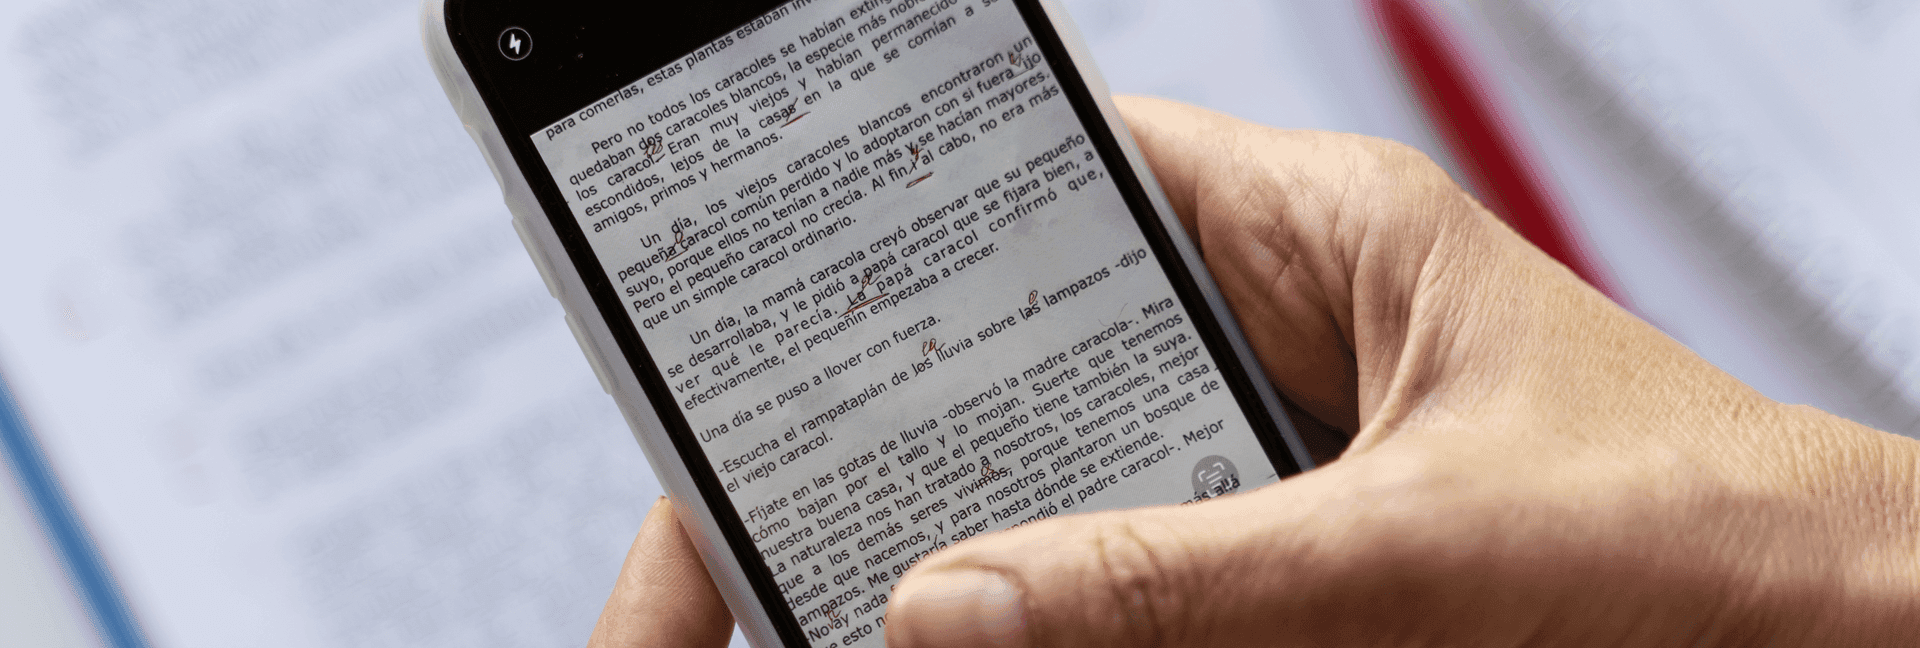
Faded documents, indistinct handwriting, and low-resolution images can make it difficult for OCR to correctly identify and interpret characters. Pattern recognition in low-quality images becomes a real puzzle, requiring advanced image processing techniques to improve text legibility.
2. Recognition of Different Fonts and Styles
Documents can be filled with diversity in terms of fonts and writing styles. OCR must be able to recognize a wide variety of fonts, from the most classic to the most modern, in addition to handling variations in character size and style. This requires training with a wide range of fonts and intelligent algorithms to adapt to these variations.
3. Recognition of Languages and Special Characters
Linguistic diversity and the presence of special characters and accents add layers of complexity to the OCR process.
It is extremely important to ensure that OCR is capable of recognizing a wide variety of languages and assigning the correct meaning to words. The misinterpretation of homonyms or a lack of understanding of context can lead to significant errors. Although OCR is impressive at recognizing characters, it still faces challenges in understanding semantic nuances.
4. Balancing Speed and Accuracy
Modern OCR is fast, but balancing this speed with accuracy is an ongoing challenge. The pursuit of high-speed text extraction often involves compromising accuracy. Complex algorithms are required to optimize this balance, ensuring that OCR does not sacrifice quality for the sake of speed.
Pita.IA: Pitang's OCR solution
To support our clients in overcoming challenges like these, Pitang has developed a platform that performs document verification and form filling through automation, and now your organization can benefit from extracting information from semi-structured documents in minutes!
With Pita.ia, it is possible to:
Automate document reading;
Receive already structured verification data;
Classify documents by category;
Track the process through data extraction.
The future of OCR promises greater accuracy, handles an even wider variety of languages and fonts, and may even explore the use of machine learning to handle complex semantic contexts.
Count on Pitang to facilitate and help you and your organization bring projects to fruition through optical character recognition. Contact us!